Validation
Strategy transparency
The MA-crossover strategy used by the agent runs through a four-stage Monte Carlo Permutation Test framework. Every stage's result is published below — including failures.
Stage 2 — IS permutation
Stage 3 — Walk-forward
Stage 4 — WF permutation
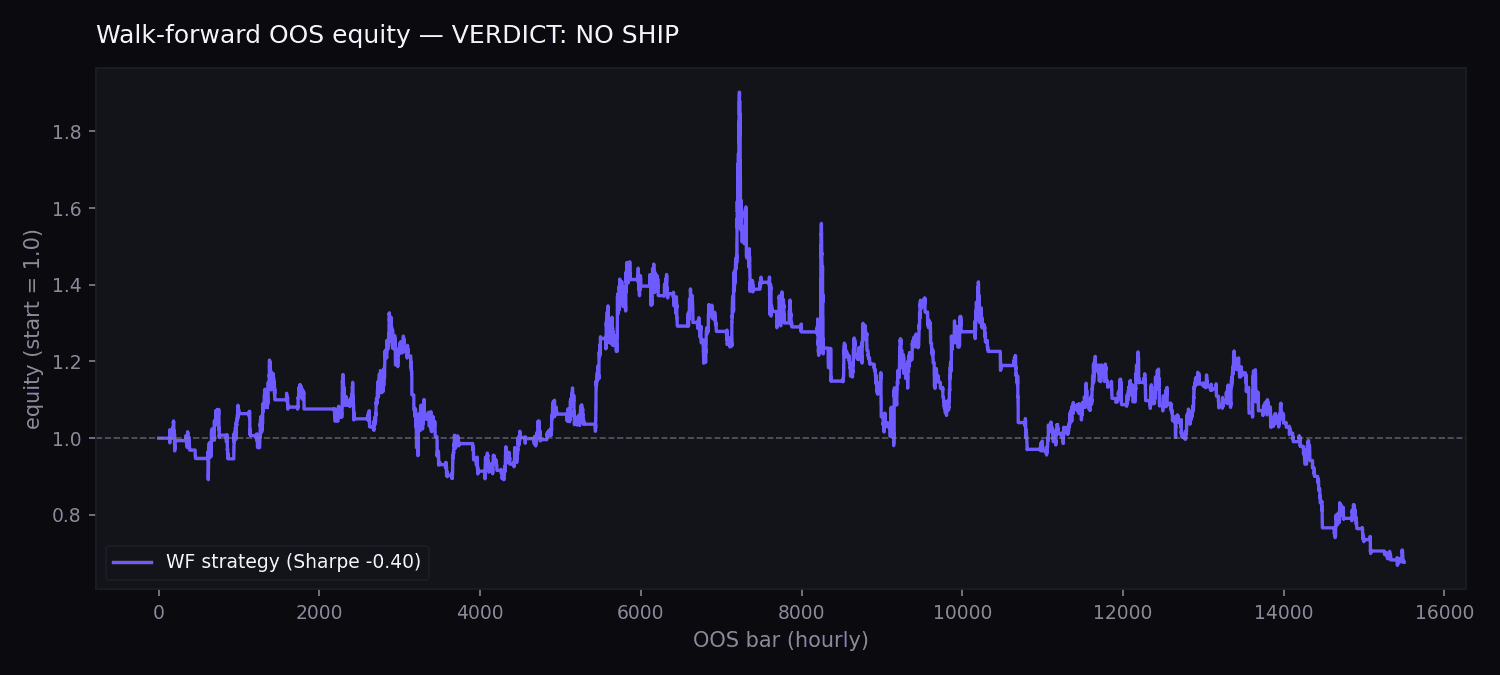
Walk-forward OOS equity
Concatenated test-window log returns, exp-cumsum
In-sample optimization
Live agent params
The agent currently runs MA(10, 30). This is the hardcoded default; given the failed verdict, treat the live signal as a demonstration only.
Holdout — bars the search never saw
5,832 hourly bars after 2026-01-01 · scored after the verdict, never fed into it
| Parameters | Sharpe | Return | Max DD | Trades |
|---|---|---|---|---|
| In-sample best MA(17, 80) | -0.124 | -3.4% | -36.3% | 105 |
| Live agent MA(10, 30) | -0.174 | -4.8% | -37.9% | 207 |
| Last walk-forward fold MA(18, 70) | +0.184 | +5.2% | -38.8% | 95 |
| Buy & hold SOL | — | -17.5% | — | — |
Provenance
A rerun over the same bars must reproduce both hashes
- Input bars · SHA-256
- 7a0698a44b01f83ef1eec97fb83ff7123af8cdd031b6c5333a0ef6af27529862
- binance SOL/USDC 1h via ccxt
- Validation artifact · SHA-256
- ed2d74884e94663918059a6b379620e0da46cdac212658e1479d09646e59f98f
If the input hash differs on your rerun, the data changed — compare nothing else until it matches. If the input hash matches and the artifact hash does not, the statistics changed.
Reproduce
All four stages and the holdout can be reproduced from the open-source pipeline. Permutations are seeded, so the p-values are exact, not approximate.
cd strategy
source .venv/bin/activate
MCPT_WORKERS=4 python scripts/run_validation.py   # writes data/validation_result.json
python scripts/export_params.py     # publishes to agent + frontend
jupyter lab notebooks/01_validate_ma_crossover.ipynb